Part 5 of my notes on empirical asset pricing
The idea in one sentence
A factor is just a long-short portfolio built from a sort. A factor model asks whether a handful of these portfolios can explain the average returns of everything else.
Post #4 showed how to find a pattern with a sort. This post is about the next question: is the pattern new, or is it something we already know about in disguise?
Step 1: Build the factors
Fama & French build each factor from a 2×3 sort: size (split at the NYSE median) × one characteristic (split at the NYSE 30th and 70th percentiles). That gives six value-weighted portfolios: Small/Big × Low/Neutral/High.
The value factor averages the small and big versions of “high minus low”: 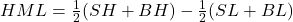
Averaging across size makes HML roughly size-neutral, so it isn’t secretly a small-stock bet. The other factors follow the same template:
| Factor | Long | Short | Avg. monthly return, 1963–2013 |
|---|---|---|---|
| RMRF (market) | Market | T-bills | 0.50% |
| SMB (size) | Small | Big | 0.29% |
| HML (value) | High B/M | Low B/M | 0.37% |
| RMW (profitability) | Robust | Weak | 0.25% |
| CMA (investment) | Conservative | Aggressive | 0.33% |
Intuition: each factor is a tradeable bet on one dimension of the cross-section, built to be as neutral as possible on size.
Step 2: The time-series regression
Take any portfolio you want to explain (a “test asset” or “left-hand-side” portfolio) and regress its monthly excess return on the factors: 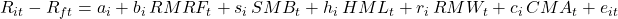
Two things come out:
- The slopes (loadings) tell you what the portfolio behaves like. A negative CMA slope means its returns move like those of aggressive investors.
- **The intercept
 (alpha)** is the average return the factors can’t explain.
The key logic: if the model is right, every intercept should be zero. Expected return is fully explained by loadings times factor premiums. A nonzero alpha means either the model is missing something or the portfolio is mispriced. That’s the joint-hypothesis problem from post #1 again.
Step 3: Test all the alphas at once (GRS)
With 25 or 32 test portfolios, you’ll get 25 or 32 alphas. Testing each one separately invites false positives. The Gibbons, Ross & Shanken (1989) test checks whether they’re jointly zero: 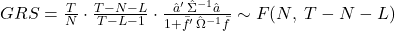
where T is the number of months, N the number of test assets and L the number of factors.
Intuition: the numerator measures how big the alphas are relative to their noise, accounting for correlation among the portfolios. The denominator scales that by how good the factors already are. There’s an equivalent reading: GRS asks whether adding the test portfolios to the factors would meaningfully improve the best achievable Sharpe ratio. If not, the factors already span the opportunity set.
Step 4: Everything gets rejected, so compare
In Fama & French (2015), GRS rejects every model for every set of test portfolios. Even in the friendliest case, p-values are below 0.04.
That’s normal. With 600 months of data, any simplified model gets rejected. So they compare models on how much they leave unexplained:
- A|aᵢ|: average absolute alpha, in return units.
- A|aᵢ| / A|rᵢ|: average absolute alpha relative to how spread out the average returns were to begin with. The five-factor model leaves about 42–54% of that dispersion unexplained, versus 54–68% for the three-factor model. The CAPM’s ratio is above 1: its alphas are more spread out than the returns themselves.
- A(α̂²) / A(μ̂²): the same idea in squared units, corrected for sampling error. Think of it as roughly “1 − R²” of a regression of expected returns on model predictions. For the five-factor model it’s often under 25%, versus over 50% for the three-factor model on some test sets.
Lesson: a model isn’t judged by whether it’s rejected, but by whether it’s rejected less than the alternatives.
Step 5: Is a factor redundant? (Spanning regressions)
Here’s a neat trick. Regress one factor on the other factors: 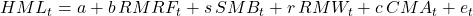
If the intercept is zero, the other four factors fully reproduce HML’s average return. Adding HML doesn’t improve the best achievable portfolio (Huberman & Kandel, 1987).
That’s exactly what Fama & French find: HML’s intercept is −0.04% per month (t = −0.47). Its premium is absorbed mostly by RMW and CMA. HML and CMA are correlated at about 0.70, which makes sense because value firms tend to invest little.
Their compromise is HMLO: HML with its explainable part removed (the intercept plus the residual from the regression above). It keeps the value loading for describing a portfolio’s tilt, but adds almost nothing to its predicted return.
Reading the slopes: a worked example
The microcap growth portfolio (smallest size, lowest B/M) is the classic troublemaker:
- Three-factor alpha: −0.49% per month (t = −5.18)
- Five-factor alpha: −0.29% (t = −3.31)
The five-factor model shrinks the alpha because the portfolio has strongly negative RMW and CMA slopes. Its returns behave like those of firms that invest a lot despite weak profitability. Those loadings predict low returns, just not low enough. That leftover is the model’s main failure.
What else plugs into this framework
The same regression is how every new factor is tested:
- Momentum (Carhart, 1997): adds UMD, the momentum long-short portfolio. Brown & Huang (2020) use this four-factor model as a robustness check for their CARs.
- Liquidity (Pástor & Stambaugh, 2003): stocks with high sensitivity to aggregate liquidity earn about 7.5% per year more after adjusting for market, size, value and momentum. That’s an alpha from exactly this kind of regression. Their liquidity factor also accounts for about half of momentum profits.
- Fama & French note that momentum and liquidity factors barely change results for their test portfolios. The slopes are near zero, unless the test assets are formed on momentum. Which factors matter depends on what you’re trying to explain.
Two interpretations of what factors “are”
Fama & French offer two readings of a zero-alpha result:
- Statistical: the market plus the factor portfolios combine into the mean-variance efficient (tangency) portfolio.
- Economic: in the spirit of Merton’s (1973) ICAPM, investors care about some unknown state variables. The factors are not those state variables. They’re diversified portfolios that happen to be exposed to them.
Neither says why profitability or investment is priced. That debate is separate from whether the model fits.
My checklist
- What are the test assets? Portfolios sorted on the same characteristics as the factors are “home turf.” Fama & French call anomaly portfolios more hostile territory.
- Is the model rejected less than the alternatives? Look at the dispersion ratios, not just GRS p-values.
- Which portfolios have the biggest alphas, and what do their slopes say they behave like?
- Is any factor redundant? Run the spanning regression.
- Is the factor neutral on size, or is it quietly a microcap bet?
Next post: Fama–MacBeth regressions, the cross-sectional alternative to everything in this post, and why the choice between weighting each month equally and weighting each observation equally matters.
References
Brown, J. R., & Huang, J. (2020). All the president’s friends: Political access and firm value. Journal of Financial Economics, 138(2), 415–431. https://doi.org/10.1016/j.jfineco.2020.05.004
Carhart, M. (1997). On persistence in mutual fund performance. Journal of Finance, 52, 57–82.
Fama, E. F., & French, K. R. (1993). Common risk factors in the returns on stocks and bonds. Journal of Financial Economics, 33, 3–56.
Fama, E. F., & French, K. R. (2015). A five-factor asset pricing model. Journal of Financial Economics, 116(1), 1–22. https://doi.org/10.1016/j.jfineco.2014.10.010
Gibbons, M., Ross, S., & Shanken, J. (1989). A test of the efficiency of a given portfolio. Econometrica, 57, 1121–1152.
Huberman, G., & Kandel, S. (1987). Mean-variance spanning. Journal of Finance, 42, 873–888.
Merton, R. (1973). An intertemporal capital asset pricing model. Econometrica, 41, 867–887.
Pástor, Ľ., & Stambaugh, R. F. (2003). Liquidity risk and expected stock returns. Journal of Political Economy, 111(3), 642–685.