Part 9 of my notes on empirical asset pricing
The idea in one sentence
A t-statistic is only as good as its standard error, and standard errors assume your observations carry independent information. In finance they almost never do.
Every post in this series ended with some version of “are the standard errors adjusted?” This one explains why that question keeps coming up.
Intuition: effective sample size
Suppose you have 10,000 firm-day returns, all from the day of the Geithner nomination. That looks like a huge sample. But every stock that day was hit by the same market-wide news. In a real sense you have one draw of “what happened that day,” observed 10,000 times.
When observations are correlated, each additional one adds less new information than an independent one would. Standard OLS formulas don’t know this. They treat 10,000 correlated observations as 10,000 independent ones, so standard errors come out too small and t-statistics too big.
A useful rule of thumb (Moulton, 1990) shows what drives the damage. With clusters of size m, the true variance is inflated by roughly: 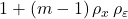
where  is the within-cluster correlation of the residuals and
 is the within-cluster correlation of the regressor.
The key insight: you need both to be correlated. If residuals are correlated within a date but your regressor varies randomly across firms, little harm is done. If the regressor is also nearly identical within the cluster (a treatment that hits a whole industry, or every firm on the same date), the bias explodes.
The two dimensions of correlation
Petersen (2009) gives the clearest framing. Finance panels have two kinds of dependence:
| Firm effect | Time effect | |
|---|---|---|
| What’s correlated | The same firm’s residuals across time | Different firms’ residuals in the same period |
| Where it comes from | Persistent firm traits your model misses | Market-wide or industry-wide shocks |
| Typical setting | Corporate finance panels (leverage, investment over years) | Asset pricing (returns in the same month) |
| Fix | Cluster by firm | Cluster by time, or use Fama–MacBeth |
Clustering means: allow arbitrary correlation within a group, assume independence across groups. You’re telling the formula which observations share information.
How the readings handle it
Each paper picks its fix based on where the correlation lives.
Bessembinder & Zhang (2013): diagnosing it. They don’t just pick a clustering choice, they test both. Clustering by deal (firm effect) barely changes their t-statistics. Clustering by date (time effect) shrinks them noticeably. Conclusion: the dependence is across firms on the same dates, so they cluster by date throughout. That’s a nice template. Try both, see which one bites, and report the conservative one.
Brown & Huang (2020): matching the cluster to the design.
- For their firm-year panel explaining who gets White House access, they cluster by firm, since the same firm shows up year after year.
- For the 2016 election, every firm shares the same event date, so clustering by time is impossible (there’s only one period). They cluster by industry, because firms in the same industry react to the election together (think energy, defense or healthcare).
Acemoglu et al. (2016): one date, few treated firms. With a single event date, you can’t cluster by time. Their fix is to estimate the full cross-firm covariance matrix from pre-event returns (250 days ending 30 days before) and use it to compute standard errors. That assumes the correlation structure before the event carries over to the event window.
They then go further with placebo inference (post #8), which sidesteps the standard-error formula entirely. Their check is revealing: on 100 non-event days, plain OLS finds a “significant” connection effect 19 times at the 5% level, when about 5 would be expected by chance. That’s what understated standard errors look like in practice.
Fama–MacBeth: time effects for free. As post #6 explained, computing the standard error from the time series of monthly slopes automatically handles correlation across firms within a month. But it does not handle firm effects: persistent characteristics make the monthly slopes autocorrelated. That’s why researchers often add a Newey–West correction to the slope series.
Jegadeesh & Titman (1993): avoiding overlap by design. Holding a portfolio for K months and starting a new one every month creates overlapping returns, which are mechanically autocorrelated. Their overlapping-cohort method (post #4) averages the K live cohorts into one non-overlapping monthly return, so ordinary time-series standard errors work again.
GRS (post #5): correlation across portfolios. The GRS test uses the full residual covariance matrix of the test portfolios, so it accounts for the fact that 25 size-B/M portfolios don’t produce 25 independent alphas.
When clustering itself breaks down
Clustering is not a cure-all:
- Too few clusters. Clustered standard errors are reliable with many clusters. With a handful (say, ten industries), they can be badly off. Placebo or permutation inference is safer, as in Acemoglu et al.
- Both effects at once. If residuals are correlated within firms and within dates, cluster on both dimensions (two-way clustering; Cameron, Gelbach & Miller, 2011; Thompson, 2011).
- Clustering doesn’t fix bias. It corrects the standard error, not the coefficient. A confounded estimate with perfect standard errors is still confounded.
A decision guide
| Your setting | Main correlation | Reasonable choice |
|---|---|---|
| Firm-year panel (corporate outcomes) | Within firm | Cluster by firm |
| Monthly return panel (many firms, many months) | Within month | Fama–MacBeth, or cluster by month |
| Both persistent firm traits and market shocks | Both | Two-way cluster (firm and time) |
| Many events on different dates | Within date when events overlap | Cluster by date (Bessembinder & Zhang) |
| One event date, many firms | Across firms that day | Industry clusters, pre-event covariance, or placebo inference |
| Few treated units | Everything | Placebo / permutation inference (Acemoglu et al.) |
| Overlapping holding periods | Within series over time | Non-overlapping construction or Newey–West |
My checklist
- Where does the correlation live: within firms, within dates, within industries?
- Is the regressor also constant within the cluster? That’s when the bias is worst.
- How many clusters are there? Fewer than a few dozen calls for caution.
- Did the authors try alternatives, and does significance survive the conservative one?
- Is there a placebo check showing the method doesn’t over-reject on non-event data?
Series recap: it all comes back to post #1
Looking back, every technique in this series is an answer to the joint-hypothesis problem:
- Event studies (post #2) shrink the window so the benchmark barely matters.
- Long-horizon methods (post #3) show how badly bad benchmarks mislead.
- Sorts and factors (posts #4–5) build and test the benchmarks themselves.
- Fama–MacBeth (post #6) tests many characteristics at once.
- Characteristic-balanced sorts (post #7) ask why a benchmark works.
- Matching and synthetic control (post #8) build counterfactuals when no model will do.
- Standard errors (this post) make sure we don’t mistake noise for any of the above.
The underlying question never changes: abnormal relative to what, and how sure are we?
References
Acemoglu, D., Johnson, S., Kermani, A., Kwak, J., & Mitton, T. (2016). The value of connections in turbulent times: Evidence from the United States. Journal of Financial Economics, 121(2), 368–391. https://doi.org/10.1016/j.jfineco.2015.10.001
Becker, B., Bergstresser, D. B., & Subramanian, G. (2013). Does shareholder proxy access improve firm value? Evidence from the Business Roundtable challenge. Journal of Law & Economics, 56, 127–160.
Bessembinder, H., & Zhang, F. (2013). Firm characteristics and long-run stock returns after corporate events. Journal of Financial Economics, 109(1), 83–102. https://doi.org/10.1016/j.jfineco.2013.02.009
Brown, J. R., & Huang, J. (2020). All the president’s friends: Political access and firm value. Journal of Financial Economics, 138(2), 415–431. https://doi.org/10.1016/j.jfineco.2020.05.004
Cameron, A. C., Gelbach, J. B., & Miller, D. L. (2011). Robust inference with multiway clustering. Journal of Business & Economic Statistics, 29(2), 238–249.
Fama, E. F., & MacBeth, J. (1973). Risk, return, and equilibrium: Empirical tests. Journal of Political Economy, 81, 607–636.
Greenwood, R. (2005). Short- and long-term demand curves for stocks: Theory and evidence on the dynamics of arbitrage. Journal of Financial Economics, 75, 607–649.
Jegadeesh, N., & Titman, S. (1993). Returns to buying winners and selling losers: Implications for stock market efficiency. Journal of Finance, 48(1), 65–91.
Moulton, B. R. (1990). An illustration of a pitfall in estimating the effects of aggregate variables on micro units. Review of Economics and Statistics, 72(2), 334–338.
Newey, W. K., & West, K. D. (1987). A simple, positive semi-definite, heteroskedasticity and autocorrelation consistent covariance matrix. Econometrica, 55(3), 703–708.
Petersen, M. (2009). Estimating standard errors in finance panel data sets: Comparing approaches. Review of Financial Studies, 22, 435–480.
Thompson, S. B. (2011). Simple formulas for standard errors that cluster by both firm and time. Journal of Financial Economics, 99(1), 1–10.