Part 8 of my notes on empirical asset pricing
The question
Every causal claim needs a counterfactual: what would have happened to these firms without the treatment? You never see it. A firm either met with the White House or it didn’t.
So you build a stand-in: a group of untreated firms that look enough like the treated ones that their outcomes approximate the missing counterfactual. The quality of that comparison group is the quality of the study.
Post #3 already showed the simplest version failing: matching IPO firms on just size and B/M left large differences in other characteristics, and those differences created a fake anomaly. This post covers three better tools from the readings.
Tool 1: Propensity score matching
The problem: treated firms differ from untreated firms in many ways at once. Firms that get White House meetings are bigger, lobby more, donate more and win more government contracts. Matching on ten characteristics directly is nearly impossible. You’d never find exact twins.
The trick: collapse all those characteristics into one number, the predicted probability of being treated, and match on that.
Brown & Huang (2020) do this in three steps:
- Estimate the score. Run a probit of “executives visited the White House this year” on campaign contributions, PAC contributions, lobbying, procurement contracts, size, market-to-book, past returns, market share, and year and industry fixed effects. Each firm’s fitted probability is its propensity score.
- Match. Pair each treated firm with the untreated firm whose score is closest (one-to-one nearest neighbor, with replacement, so a good control can be reused). Drop firms outside the common support, meaning treated firms with no plausible match.
- Check balance. After matching, test whether treated and control firms still differ on any characteristic. They report no significant differences.
Intuition: two firms with the same propensity score were equally “likely” to get access based on everything observable. If one got it and the other didn’t, the difference is as close to luck as the data allow.
The limitation: it only balances what you observe. If CEOs visit the White House because they privately expect good news, no observable score captures that.
Tool 2: Difference-in-differences (DiD)
Matching gives you comparable groups. DiD uses them to strip out anything that was changing for everyone anyway: 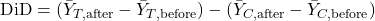
The first difference removes each group’s fixed level. The second removes shocks common to both groups.
Brown & Huang measure government procurement contracts (scaled by sales) in the 12 months before and after each visit:
| Change (pp of sales) | |
|---|---|
| Treated firms | +0.299 |
| Matched controls | −0.158 |
| Difference-in-differences | +0.457 (t = 2.16) |
Two follow-ups make this more convincing than the headline number:
- Where it comes from. About 58% of the increase is in contracts that were not awarded under full and open competition and not performance-based, the kind with the most official discretion. That’s the channel you’d expect if access matters.
- A second outcome. They classify regulatory news as positive or negative using the Loughran-McDonald (2011) word lists. Treated firms see relatively more favorable regulatory news after visits than controls.
The key assumption: parallel trends. Without the treatment, the two groups would have moved in parallel. You can’t prove it, but you can support it: show that pre-treatment trends look similar, and make sure the comparison group is well matched to begin with. That’s why matching and DiD are used together.
Tool 3: Synthetic control
Acemoglu et al. (2016) face a harder version of the problem. Geithner-connected firms were few (as few as 12 in the base sample), large and unusual. No single control firm resembles Citigroup or Blackstone.
The idea: if no real twin exists, build one. For each treated firm, find a weighted average of control firms that tracked its returns as closely as possible before the event: 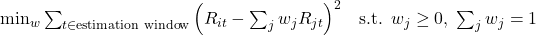
The constraints keep the synthetic firm a genuine portfolio of real firms, with no shorting and no leverage. For Bank of America, for example, Wells Fargo gets a weight of 0.30. The estimation window is the same 250 days ending 30 days before the event, as in post #2.
After the event, the treated firm’s return minus its synthetic twin’s return is the effect. They average across treated firms, giving more weight to firms whose synthetic match fit better before the event.
Intuition: the synthetic firm is a custom-made benchmark that behaved like the treated firm, not just one that looks like it on paper. It captures unobserved common drivers that characteristic matching would miss.
Inference by placebo
How do you know a 6% gap isn’t just noise? Acemoglu et al. use placebo inference:
- Randomly draw 5,000 fake “treatment groups” from the control firms, each the same size as the real one.
- Run the identical synthetic-control procedure on each.
- The real effect is significant at 5% if it falls outside the middle 95% of placebo effects.
No distributional assumptions needed: the data generate their own null distribution.
They also validate the method. Testing the “connection effect” on 100 non-event days, OLS finds significance at the 5% level 19 times (you’d expect about 5 by chance). Synthetic matching finds it 4 times. OLS was picking up spurious co-movement among connected firms. Synthetic control wasn’t.
The result: connected firms earn about 6.0% over [0, 1] and 12.4% over [0, 10] relative to their synthetic twins. The effect is larger for highly connected firms.
Falsification: the tests that persuade
A good comparison group is necessary but not sufficient. The strongest papers also show the effect doesn’t appear where it shouldn’t:
| Test | Logic | Result |
|---|---|---|
| Other crisis events (Bear Stearns, Lehman, AIG, TARP injections) | If connected firms just react more to any crisis news, they’d move here too | No significant effect (Acemoglu et al.) |
| Rival Treasury candidates (Summers, Corzine, Volcker, Bair) | If some hidden trait makes firms “well connected” generally, links to rivals would matter too | Not significant (Acemoglu et al.) |
| Earlier Treasury Secretaries | Connections should matter only in turbulent times | Goldman Sachs fell when Paulson was nominated in 2006 |
| Reversal event | If the effect is real, bad news for the connection should reverse it | Connected firms fell when Geithner’s tax problems surfaced |
| Pre-trends | Effect shouldn’t appear before the news | No consistent pattern before the nomination |
| Cancelled meetings | If the meeting itself matters, cancelled ones shouldn’t | Insignificant CARs (Brown & Huang) |
| Drop influential firms | One firm shouldn’t drive everything | Dropping Blackstone weakens OLS but not synthetic results |
Natural experiments: letting history pick the treatment
Brown & Huang add one more design that sidesteps selection entirely. Firms choose when to visit the White House. But nobody chose the 2016 election result. The date was fixed in advance, and prediction markets gave Clinton roughly an 80% chance. Trump’s win was a negative shock to firms with Obama-era access.
Firms with access underperformed similar firms by about 70 basis points in three days, and closely connected firms by more. Because the shock’s timing wasn’t chosen by the firms, the “CEOs visit when they have good private news” story can’t explain it.
Choosing a tool
| Situation | Tool | Example |
|---|---|---|
| Many treated firms, rich observables | Propensity score matching + DiD | Brown & Huang, procurement contracts |
| Few, unusual treated firms, long pre-event return history | Synthetic control with placebo inference | Acemoglu et al., Geithner |
| Treatment timing firms didn’t choose | Natural experiment / event study | Brown & Huang, 2016 election |
| Long-run returns | Control for characteristic differences directly | Bessembinder & Zhang |
My checklist
- What’s the counterfactual, and why is the comparison group a believable stand-in?
- Are the groups balanced after matching? Is there common support?
- Is parallel trends plausible? Are pre-event trends shown?
- Who chose the treatment timing? If firms did, what rules out private information?
- How is inference done? Placebos, or standard errors that assume independence?
- What falsification tests are there? Where shouldn’t the effect appear?
Next and final post: standard errors in finance panels. Clustering by firm, date or industry, and why the choice can make or break a t-statistic.
References
Abadie, A., Diamond, A., & Hainmueller, J. (2010). Synthetic control methods for comparative case studies: Estimating the effect of California’s tobacco control program. Journal of the American Statistical Association, 105, 493–505.
Abadie, A., & Gardeazabal, J. (2003). The economic costs of conflict: A case study of the Basque country. American Economic Review, 93, 113–132.
Acemoglu, D., Johnson, S., Kermani, A., Kwak, J., & Mitton, T. (2016). The value of connections in turbulent times: Evidence from the United States. Journal of Financial Economics, 121(2), 368–391. https://doi.org/10.1016/j.jfineco.2015.10.001
Bessembinder, H., & Zhang, F. (2013). Firm characteristics and long-run stock returns after corporate events. Journal of Financial Economics, 109(1), 83–102. https://doi.org/10.1016/j.jfineco.2013.02.009
Brown, J. R., & Huang, J. (2020). All the president’s friends: Political access and firm value. Journal of Financial Economics, 138(2), 415–431. https://doi.org/10.1016/j.jfineco.2020.05.004
Heckman, J., Ichimura, H., & Todd, P. (1997). Matching as an econometric evaluation estimator: Evidence from evaluating a job training program. Review of Economic Studies, 64, 605–654.
Loughran, T., & McDonald, B. (2011). When is a liability not a liability? Textual analysis, dictionaries, and 10-Ks. Journal of Finance, 66, 35–65.