Part 1 of my notes on empirical asset pricing
The one idea everything else rests on
Every paper in empirical finance eventually makes a claim like “this stock earned an abnormal return.” That sounds like a fact about the stock. It isn’t. It’s a fact about the stock and the model you used to decide what “normal” was. 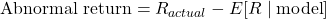
Only  is observed. The second term is a guess from a model you picked. So whenever you find something “abnormal,” there are always two possible explanations:
- The market got it wrong (prices didn’t reflect information properly), or
- Your model got it wrong (you mismeasured what “normal” should be).
You can’t separate the two with the data alone. Fama (1991) put it bluntly: “market efficiency per se is not testable.” It can only be tested jointly with an asset-pricing model. That’s the joint-hypothesis problem.
An intuition: two thermometers
Suppose a thermometer reads 3 degrees higher than your reference thermometer. Is the first one broken, or is the reference miscalibrated? You can’t tell without a third, trusted instrument. In finance there is no trusted third instrument. Every benchmark (CAPM, Fama-French 3 or 5 factors, matched control firms) is itself a model that is known to be imperfect.
Why horizon changes everything
Here’s the part that made it click for me. How much the bad-model problem hurts depends on how long you measure.
Short windows (days): the model barely matters. A typical stock’s expected daily return is a few hundredths of a percent. Even if your model is off by a lot in relative terms, the error over one or two days is tiny next to a big price move.
Acemoglu et al. (2016) is a good example. When news leaked that Timothy Geithner would be nominated Treasury Secretary, financial firms connected to him earned roughly 6% abnormal returns within about a day. They used a plain market model (a 250-day estimation window ending 30 days before the event). Nobody seriously argues that a 6% one-day jump comes from getting beta slightly wrong. The signal swamps any plausible model error. This is why Fama calls short-window event studies the cleanest evidence we have.
Long windows (years): the model is everything. Stretch the window to 3 or 5 years and small monthly model errors compound. Now the benchmark choice can create or erase an entire “anomaly.”
Bessembinder & Zhang (2013) is the cleanest demonstration. Earlier studies found that firms issuing seasoned equity (SEOs) underperform for five years afterward, which looks like investors being fooled. Bessembinder & Zhang kept the event and changed only the benchmark:
- Matching on size and book-to-market only: SEO firms end up about 15% behind their matched firms (a wealth relative of 0.85).
- Also controlling for idiosyncratic volatility, liquidity, momentum, investment and beta: the gap goes to essentially zero.
The IPO, merger-bidder and dividend-initiation “anomalies” disappear the same way. The market didn’t change. The definition of “normal” did.
Every model is wrong, so compare them
If all benchmarks are imperfect, what do researchers do? They stop asking “is this model true?” and start asking “which model fails least?”
Fama & French (2015) is explicit about this. Their formal test (the GRS test, which asks whether all model alphas are jointly zero) rejects every model they consider, including their own five-factor model. They still conclude the five-factor model is better, because it leaves less return unexplained than the three-factor model. Rejection is the default. Relative performance is the real result.
How this shows up in every paper
Once you see the problem, you notice that most empirical designs are ways to shrink it:
| Design choice | How it fights the bad-model problem | Example |
|---|---|---|
| Very short event windows | Makes expected-return errors negligible | Geithner nomination (Acemoglu et al.) |
| Richer benchmarks | Adds characteristics or factors that explain “normal” | Five-factor model; Bessembinder-Zhang controls |
| Matched control firms | Compares against similar firms instead of a formula | Size/BM-matched firms; propensity-score matching (Brown & Huang 2020) |
| Placebo and falsification tests | Checks whether the “effect” shows up where it shouldn’t | Rival Treasury candidates; cancelled White House visits |
| Robustness to alternative benchmarks | If the result survives several models, it’s less likely a model artifact | Brown & Huang rerun CARs with industry-adjusted, Carhart and DGTW benchmarks |
My takeaway
When I read “firms earned abnormal returns of X%,” I now ask three questions:
- Abnormal relative to what? Which model defined “normal”?
- Over what horizon? Days (model barely matters) or years (model is everything)?
- Would a different benchmark kill it? Did the authors check?
Next post: the short-window event study itself. How CARs are built, why the estimation window sits before the event, and what goes wrong when many firms share the same event date.
References
Acemoglu, D., Johnson, S., Kermani, A., Kwak, J., & Mitton, T. (2016). The value of connections in turbulent times: Evidence from the United States. Journal of Financial Economics, 121(2), 368–391. https://doi.org/10.1016/j.jfineco.2015.10.001
Bessembinder, H., & Zhang, F. (2013). Firm characteristics and long-run stock returns after corporate events. Journal of Financial Economics, 109(1), 83–102. https://doi.org/10.1016/j.jfineco.2013.02.009
Brown, J. R., & Huang, J. (2020). All the president’s friends: Political access and firm value. Journal of Financial Economics, 138(2), 415–431. https://doi.org/10.1016/j.jfineco.2020.05.004
Fama, E. F. (1991). Efficient capital markets: II. Journal of Finance, 46(5), 1575–1617. https://doi.org/10.1111/j.1540-6261.1991.tb04636.x
Fama, E. F., & French, K. R. (2015). A five-factor asset pricing model. Journal of Financial Economics, 116(1), 1–22. https://doi.org/10.1016/j.jfineco.2014.10.010
Gibbons, M. R., Ross, S. A., & Shanken, J. (1989). A test of the efficiency of a given portfolio. Econometrica, 57(5), 1121–1152. https://doi.org/10.2307/1913625