Part 6 of my notes on empirical asset pricing
The idea in one sentence
Instead of one giant regression over all stocks and all months, run a separate cross-sectional regression every month, then treat the monthly slopes as a time series and average them.
Posts #4 and #5 worked with portfolios. Fama–MacBeth works with individual stocks (or portfolios) directly and lets you control for several characteristics at once, which a sort struggles to do.
The recipe
Step 1. For each month t, regress returns across stocks on characteristics known at the start of the month: 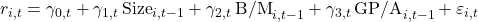
That gives you one set of slopes per month: 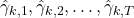 .
Step 2. Average each slope over time and use its time-series variation for the standard error: 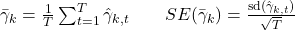
A t-stat on  tells you whether the characteristic reliably predicts returns holding the others fixed.
Intuition 1: each month is one experiment
Think of every month as an independent trial of “do high-profitability stocks outperform this month, controlling for size and value?” Some months the answer is yes, some no. Fama–MacBeth asks whether the average answer is reliably positive.
This is why the standard errors come out right even though stocks within a month are correlated. The whole month’s market-wide shock is baked into that month’s  . The noise shows up as month-to-month variation in the slope, which is exactly what the standard error measures. You never have to model the cross-firm correlation directly. This is the same problem that forced Acemoglu et al. to build a special covariance correction in post #2.
Intuition 2: each slope is a portfolio return
This is the insight that makes Fama–MacBeth click. Each monthly slope  is mathematically the return on a zero-cost portfolio that has:
- a unit exposure to characteristic k, and
- zero exposure to every other characteristic in the regression.
So a Fama–MacBeth regression is really a sort done by regression: it builds a long-short portfolio for each characteristic, perfectly neutralized against the others, every month. The average slope is that portfolio’s average return. This connects directly back to post #4.
Where it shows up in the readings
Novy-Marx (2013) uses Fama–MacBeth regressions to show that gross profits-to-assets predicts returns about as strongly as book-to-market, controlling for B/M, size and momentum. He also points out that earlier work was mixed: Fama & French (2006) found earnings helped in Fama–MacBeth regressions, while Fama & French (2008) found profitability sorts produced weak spreads. The measure turned out to matter. Gross profitability works much better than earnings. It’s also a reminder that regressions and sorts can tell different stories.
Bessembinder & Zhang (2013) use it the other way around, as a robustness check. They estimate their long-run abnormal return regression (from post #3) two ways:
| Pooled OLS | Fama–MacBeth | |
|---|---|---|
| Weights | Each event equally | Each month equally |
| Standard errors | Clustered by date | From time-series variation of monthly slopes |
| Economic reading | Relevant if an investor’s capital scales with the number of events | Relevant if an investor commits constant capital every month |
The IPO, SEO, merger and dividend-initiation anomalies are insignificant under both once characteristics are controlled for. When two different weighting schemes agree, the conclusion is much sturdier. They also require at least 20 firms per month, because a regression on a handful of stocks produces wild slopes that distort the average.
Fama–MacBeth vs. the other tools
| Portfolio sort | Time-series factor regression | Fama–MacBeth | |
|---|---|---|---|
| Unit | Portfolios | Portfolios (or factors) | Individual stocks (or portfolios) |
| Controls for many variables at once | Hard (cells go empty) | Through factor loadings | Easy, just add regressors |
| Assumes linearity | No | In the factors | Yes, in characteristics |
| Output | Spread in average returns | Alphas and loadings | Premium per unit of characteristic |
| Best for | Seeing the shape of an effect | Testing whether known factors explain it | Testing marginal effects with many controls |
Pitfalls
1. Microcaps dominate. Ordinary least squares gives every stock equal weight, and there are thousands of tiny stocks. A characteristic can look powerful in Fama–MacBeth just because it works among microcaps. Common fixes are to drop the smallest stocks, weight by market cap, or check results by size group.
2. Outliers and scale. Raw characteristics like B/M have extreme values that swing individual monthly slopes. Researchers often use logs, winsorize, or rank-transform. Bessembinder & Zhang rank-normalize each characteristic difference to lie between −1 and 1, which also makes the coefficients directly comparable.
3. Linearity. A characteristic might only matter at the extremes. Adding squared terms, as Bessembinder & Zhang do, can change conclusions. That’s exactly what killed the merger and dividend anomalies.
4. Persistent slopes. The standard error assumes the monthly slopes are roughly independent over time. When characteristics barely change from month to month, the slopes can be autocorrelated and the standard error too small. The usual fix is a Newey–West adjustment on the slope series. Petersen (2009) shows Fama–MacBeth doesn’t handle persistent firm effects well.
5. Estimated betas. If the regressors are estimated betas rather than observed characteristics, measurement error biases slopes toward zero (errors-in-variables). The original Fama–MacBeth paper used portfolio betas to reduce the noise. Pástor & Stambaugh (2003) follow the same logic: they sort stocks on predicted liquidity betas and report betas for the resulting portfolios rather than noisy individual estimates. Shanken (1992) provides the standard-error correction for this two-pass setup.
My checklist
- Are the characteristics known before the month starts?
- Are microcaps driving the result? Check with value weights or size subsamples.
- How are extreme values handled? Logs, winsorizing or ranks?
- Are the regressors characteristics or estimated betas? If betas, is errors-in-variables addressed?
- Are the standard errors adjusted for autocorrelation in the slopes?
- Does the result match the portfolio sort? If not, why?
Next post: characteristics vs. covariances. Daniel & Titman’s test of whether stocks earn premiums because of what they are or because of how they move.
References
Bessembinder, H., & Zhang, F. (2013). Firm characteristics and long-run stock returns after corporate events. Journal of Financial Economics, 109(1), 83–102. https://doi.org/10.1016/j.jfineco.2013.02.009
Fama, E. F., & French, K. R. (2006). Profitability, investment, and average returns. Journal of Financial Economics, 82, 491–518.
Fama, E. F., & French, K. R. (2008). Dissecting anomalies. Journal of Finance, 63, 1653–1678.
Fama, E. F., & MacBeth, J. (1973). Risk, return, and equilibrium: Empirical tests. Journal of Political Economy, 81, 607–636.
Newey, W. K., & West, K. D. (1987). A simple, positive semi-definite, heteroskedasticity and autocorrelation consistent covariance matrix. Econometrica, 55(3), 703–708.
Novy-Marx, R. (2013). The other side of value: The gross profitability premium. Journal of Financial Economics, 108(1), 1–28. https://doi.org/10.1016/j.jfineco.2013.01.003
Pástor, Ľ., & Stambaugh, R. F. (2003). Liquidity risk and expected stock returns. Journal of Political Economy, 111(3), 642–685.
Petersen, M. (2009). Estimating standard errors in finance panel data sets: Comparing approaches. Review of Financial Studies, 22, 435–480.
Shanken, J. (1992). On the estimation of beta-pricing models. Review of Financial Studies, 5(1), 1–33.